Cilium Service Mesh: The Sidecar-Free eBPF Mesh on Kubernetes 1.37
Cilium is the default answer today when platform teams list their CNI requirements: eBPF datapath, kube-proxy replacement, identity-based network policy, and Hubble flow visibility without touching a single application container. But the pitch usually stops there. The interesting question for a platform engineer in late 2026 is no longer "which CNI?" — it is "do we still need a separate service mesh, or can the CNI absorb it?"
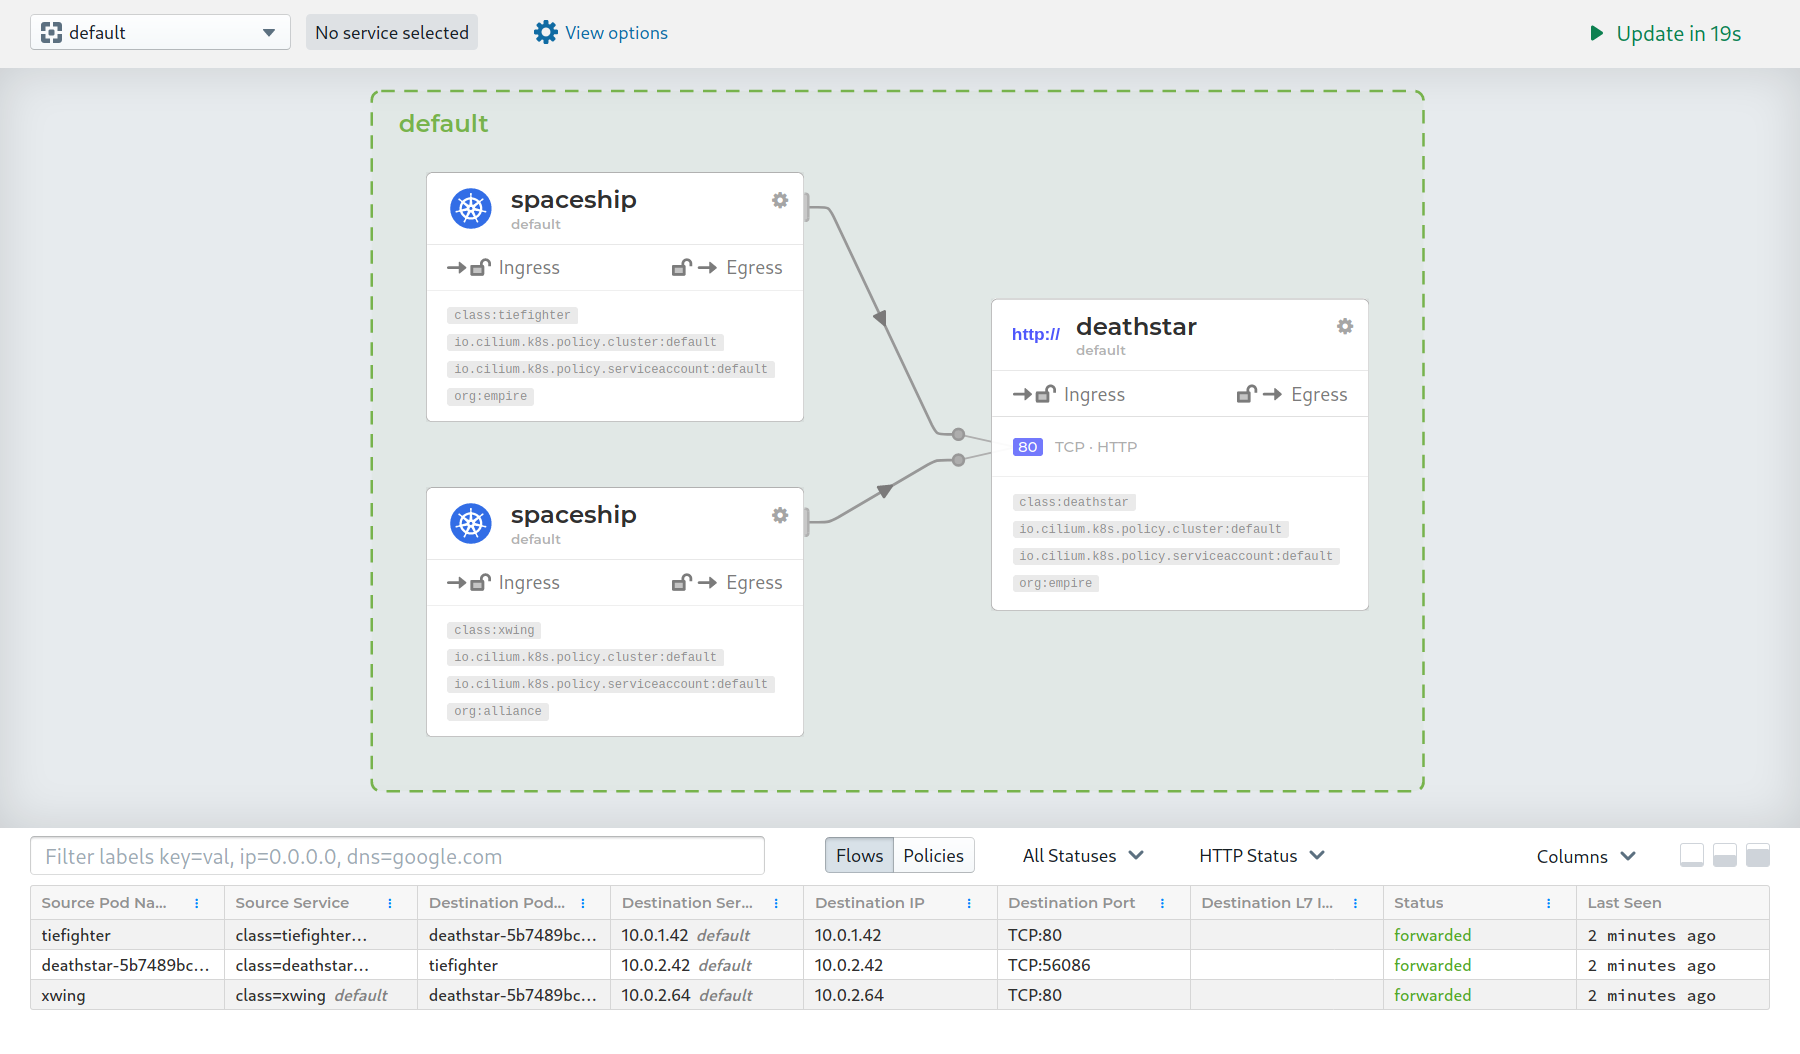
This guide takes the second question seriously. We walk the full sidecar-free mesh stack you can assemble with Cilium 1.20 on Kubernetes 1.37: the eBPF datapath for L3/L4, the per-node Envoy for L7, ztunnel for in-path mTLS, Gateway API v1.6 for north-south traffic, Hubble for observability, and ClusterMesh for multi-cluster. Every manifest here is complete and runnable. Nothing is a sketch.
We also spend a lot of time on the parts vendor blogs skip: what breaks when you delete kube-proxy, why L7 policy and ztunnel mTLS fight each other, the exact upgrade sequence for Gateway API CRDs, and which workloads should never enroll in the mesh. By the end you should be able to decide — with numbers and commands, not vibes — whether Cilium Service Mesh replaces the sidecar tax in your platform, or whether you genuinely still need Istio's waypoint model.
TL;DR
- Adopt if: you already run Cilium as CNI, your mesh needs are dominated by mTLS + L3/L4 segmentation + L7 policy on a subset of services, and you want Gateway API as the single north-south API.
- Skip if: you need per-workload L7 routing everywhere (VirtualService-style traffic shifting), you depend on Kafka-aware policies (removed in 1.18), or your platform already standardized on Istio ambient with waypoints — Cilium's ztunnel integration is Beta and ClusterMesh-incompatible as of 1.20.
- Key upgrade trap: Cilium 1.20 requires Gateway API v1.6.1 minimum, and TLSRoute moved to v1 — installing the Standard v1.6.1 channel's TLSRoute CRD without the Experimental channel's v1alpha2 makes existing TLSRoute objects invisible to the API server. This is a data-visibility outage, not a graceful degradation.
- Resource win: one Envoy DaemonSet and one ztunnel DaemonSet for the whole cluster, instead of one proxy container per pod. On a 50-node cluster running 30 pods per node, that is roughly 1,500 sidecars replaced by ~100 node-local processes.
Why Sidecars Lost the Argument
The sidecar model charged every pod a fixed tax: CPU shares, memory floor (~50–100 MB per proxy), startup coupling, and an upgrade campaign every time the mesh control plane revved. The last one is the killer at fleet scale — a sidecar mesh upgrade means a rolling restart of every pod in the fleet, coordinated with HPA churn and deployment windows. An eBPF mesh upgrades the DaemonSet, and the fleet keeps serving.
Cilium's answer is architectural, not cosmetic. Instead of putting a proxy next to every workload, it puts the datapath functions under them:
- L3/L4 (connectivity, service load balancing, NAT, ACLs, encryption) runs in eBPF programs attached to the veth/netkit devices of each pod, in-kernel, on every packet — no proxy hop at all.
- L7 (HTTP/gRPC routing, header policy, rate limiting) only pays for the per-node Envoy when a policy actually requires it. If no L7 rule selects the flow, traffic never leaves the kernel.
- mTLS is now available in two flavors: the mature IPsec/WireGuard transparent encryption between nodes, and the newer ztunnel in-path HBONE mTLS for enrolled namespaces (Beta in 1.20).
The result is that the "mesh" is no longer a thing you install next to your platform. It is a set of capabilities your CNI already ships, and a set of CRDs you apply selectively. The rest of this guide is the operating manual for those capabilities.
Architecture: What Runs Where
Before manifests, get the component map right. A full Cilium Service Mesh installation on Kubernetes 1.37 consists of:
The Four Planes
- Agents (DaemonSet
cilium): one per node; compiles and attaches eBPF programs, enforces policy, programs service load balancing (BPF LB / Maglev), and redirects L7-matched flows to the node-local Envoy via TPROXY. - Operator (Deployment
cilium-operator): IPAM, Node Init, ClusterMesh API server management, BGP control plane reconciliation, and (in 1.20) the ztunnel enrollment reconciler that registers SPIFFE identities with SPIRE inspireCA mode. - Envoy (DaemonSet
cilium-envoy): the per-node L7 engine. Ingress, Gateway API, and L7 CiliumNetworkPolicy rules all compile down to xDS config streamed to this shared proxy. One process per node, not one per pod. - Hubble (in-agent) + Relay (Deployment) + UI: flow observation on every node, aggregated by a single relay, queryable by CLI or the Hubble UI deployed as its own chart.
And the data path a packet actually takes:
  Pod A (source)                       Pod B (destination)
 ┌──────────────┐                     ┌──────────────┐
 │  app container│                    │  app container│
 └──────┬───────┘                     └──────▲───────┘
        │ send()                             │ deliver()
 ┌──────▼───────────────────────────────────┴───────┐
 │  Pod A's netns (veth/netkit)                     │
 │   ├─ eBPF (from-container): policy check L3/L4   │
 │   └─ L7 rule matched? ── TPROXY ──► Envoy (node) │
 │                                      │ xDS route │
 │                                      ▼           │
 │  Node kernel: BPF LB / Maglev pick backend       │
 │   ├─ same node: deliver to Pod B netns directly  │
 │   └─ cross node: encapsulate (VXLAN/GENEVE) or   │
 │      route (native), [optional IPsec/WG, or     │
 │      ztunnel HBONE 15008 for mTLS]               │
 └──────────────────────────────────────────────────┘
Three things to internalize from this diagram, because they drive every trade-off later:
- The kernel path is the default. Only flows explicitly selected by an L7 rule take the Envoy hop. Everything else is wire-speed in-kernel forwarding.
- Envoy is per node, so L7 capacity is per node. A single hot pod with 20k RPS of HTTP policy does not get its own proxy; it shares the node's Envoy with every other L7-matched flow on that node. Capacity-plan Envoy DaemonSet resources accordingly.
- ztunnel changes the picture at the pod netns edge. When a namespace is enrolled, iptables rules inside each pod's network namespace redirect supported TCP flows to the node-local ztunnel, which tunnels them via HBONE (mTLS over HTTP/2 CONNECT, port 15008). This is why ztunnel mTLS and L4/L7 policy interact in non-obvious ways — policy that used to see the real 5-tuple now sees the tunnel.
Prerequisites & System Requirements
Cilium 1.20 requires Linux kernel >= 5.10 (or the equivalent backport, e.g. 4.18 on RHEL 8.10), AMD64 or AArch64 nodes, and iptables/netfilter kernel options present for masquerading, tunneling, and the L7/FQDN proxy features. Managed offerings lower the bar further: GKE with the Cilium datapath, EKS with the AmazonLinux 2/Bottlerocket AMIs, AKS with Azure CNI powered by Cilium — each ships a kernel that meets the requirements.
Verify before you install:
# Kernel and arch
uname -r            # expect >= 5.10, or 4.18 on RHEL 8.10
uname -m            # x86_64 or aarch64

# Required netfilter options (module names per docs.cilium.io System Requirements)
for opt in CONFIG_NETFILTER_XT_SET CONFIG_NETFILTER_XT_MATCH_COMMENT \
           CONFIG_NETFILTER_XT_TARGET_MARK CONFIG_NETFILTER_XT_TARGET_TPROXY; do
  grep -q "$opt=[my]" "/boot/config-$(uname -r)" && echo "$opt OK" || echo "$opt MISSING"
done

# Kubernetes version context (guide targets 1.37)
kubectl version --short 2>/dev/null || kubectl version --output=yaml | head -6
Kernel gotcha: the container image ships its own clang+LLVM >= 18.1 toolchain for runtime compilation where needed, so you do not need clang on the host — but the kernel config options above are non-negotiable. On minimal node images (Flatcar, custom Talos configs), verify TPROXY support specifically: with the default bpf.tproxy=false, L7 redirection uses iptables TPROXY, and nodes missing those modules will silently blackhole Gateway API traffic that "should work."
Reference Installation: Helm Values for a Mesh-Ready Cluster
The Cilium Helm chart is the source of truth for a production install. The values below enable the full mesh stack on a fresh cluster: kube-proxy replacement, L7 Envoy, Hubble with Relay, Gateway API controller, and ztunnel mTLS. Apply it with the 1.20.2 chart:
# cilium-values.yaml — Cilium 1.20.2, mesh-ready reference install
kubeProxyReplacement: true          # replace kube-proxy with BPF LB
k8sServiceHost: <API_SERVER_IP>    # required when kube-proxy is removed
k8sServicePort: 6443

# --- Datapath ---
# bpf.datapathMode=auto probes each host for netkit (kernel >= 6.8)
# and falls back to veth on the rest of a mixed fleet (new in 1.20)
bpf:
  datapathMode: auto               # default remains "veth"
  tproxy: false                    # default: iptables-based TPROXY for the L7 proxy

routingMode: tunnel                # or "native" with direct routing
operator:
  replicas: 2

# --- L7 / Envoy ---
l7Proxy: true                      # required for L7 policy + Ingress + Gateway API
envoy:
  enabled: true                    # dedicated cilium-envoy DaemonSet

# --- Gateway API ---
gatewayAPI:
  enabled: true                    # requires Gateway API CRDs >= v1.6.1 (see below)

# --- Hubble ---
hubble:
  enabled: true
  relay:
    enabled: true
  metrics:
    enabled:
      - dns
      - drop
      - tcp
      - flow
      - icmp
      - http

# --- ztunnel mTLS (Beta in 1.20) ---
encryption:
  enabled: true
  type: ztunnel                    # was "ipsec" or "wireguard" for transparent-only
  ztunnel:
    ca:
      type: internal               # 'spire' for the SPIFFE/SPIRE identity stack
Two values here are capacity decisions, not defaults. operator.replicas should be 2+ in any cluster you care about (the operator runs the ztunnel enrollment reconciler and IPAM; one replica is a SPOF). And because Envoy is shared per node, size the Envoy DaemonSet's resources against your real per-node L7 RPS rather than shipping the chart defaults — the node-local proxy is now the L7 budget for every pod scheduled on that node.
Install:
# Gateway API CRDs FIRST — Cilium 1.20 requires v1.6.1 minimum.
# Standard channel first:
kubectl apply --server-side -f https://raw.githubusercontent.com/kubernetes-sigs/gateway-api/v1.6.1/config/crd/standard/gateway.networking.k8s.io_gatewayclasses.yaml
kubectl apply --server-side -f https://raw.githubusercontent.com/kubernetes-sigs/gateway-api/v1.6.1/config/crd/standard/gateway.networking.k8s.io_gateways.yaml
kubectl apply --server-side -f https://raw.githubusercontent.com/kubernetes-sigs/gateway-api/v1.6.1/config/crd/standard/gateway.networking.k8s.io_httproutes.yaml
kubectl apply --server-side -f https://raw.githubusercontent.com/kubernetes-sigs/gateway-api/v1.6.1/config/crd/standard/gateway.networking.k8s.io_referencegrants.yaml
kubectl apply --server-side -f https://raw.githubusercontent.com/kubernetes-sigs/gateway-api/v1.6.1/config/crd/standard/gateway.networking.k8s.io_grpcroutes.yaml
kubectl apply --server-side -f https://raw.githubusercontent.com/kubernetes-sigs/gateway-api/v1.6.1/config/crd/standard/gateway.networking.k8s.io_backendtlspolicies.yaml
kubectl apply --server-side -f https://raw.githubusercontent.com/kubernetes-sigs/gateway-api/v1.6.1/config/crd/standard/gateway.networking.k8s.io_tlsroutes.yaml
# Experimental channel (ListenerSets, TCPRoute/UDPRoute in this cycle):
kubectl apply --server-side -f https://raw.githubusercontent.com/kubernetes-sigs/gateway-api/v1.6.1/config/crd/experimental/gateway.networking.k8s.io_listenersets.yaml
kubectl apply --server-side -f https://raw.githubusercontent.com/kubernetes-sigs/gateway-api/v1.6.1/config/crd/experimental/gateway.networking.k8s.io_tcproutes.yaml
kubectl apply --server-side -f https://raw.githubusercontent.com/kubernetes-sigs/gateway-api/v1.6.1/config/crd/experimental/gateway.networking.k8s.io_udproutes.yaml

# Then Cilium itself:
helm upgrade --install cilium cilium/cilium --version 1.20.2 \
  --namespace kube-system \
  --values cilium-values.yaml --wait

# Generate and apply the ztunnel CA/bootstrap secrets (see next section for full script)
bash generate-ztunnel-secrets.sh

# Confirm the stack:
cilium status --wait
cilium hubble enable   # no-op if Helm already enabled it; patches ConfigMap if needed
Do not skip the secrets step with ztunnel. The ztunnel integration requires a pre-created Kubernetes secret (cilium-ztunnel-secrets) containing bootstrap and CA keys before the agents will come up. This follows the same injection pattern as IPsec key rotation, and unlike the chart's certgen mode used for Hubble/ClusterMesh certs, it is on you to create them. The full generation script is below.
#!/usr/bin/env bash
# SPDX-License-Identifier: Apache-2.0
set -eu

workdir=$(mktemp -d)
cd "$workdir"

# == Bootstrap identity (secures ztunnel <-> Cilium xDS/cert server) ==
openssl genrsa -out bootstrap-private.key 2048

cat > openssl.conf <<'EOF'
[ req ]
distinguished_name = req_distinguished_name
x509_extensions = v3_ca
prompt = no

[ req_distinguished_name ]
O = cluster.local

[ v3_ca ]
subjectKeyIdentifier = hash
authorityKeyIdentifier = keyid:always,issuer
basicConstraints = CA:FALSE
keyUsage = digitalSignature, keyEncipherment
extendedKeyUsage = serverAuth, clientAuth
subjectAltName = @alt_names

[alt_names]
DNS.1 = localhost
EOF

openssl req -x509 -new -nodes -key bootstrap-private.key -sha256 -days 3650 \
  -out bootstrap-root.crt -config openssl.conf

# == CA (signs ephemeral in-memory workload certs issued to ztunnel) ==
openssl genrsa -out ca-private.key 2048

cat > ca-openssl.conf <<'EOF'
[ req ]
distinguished_name = req_distinguished_name
x509_extensions = v3_ca
prompt = no

[ req_distinguished_name ]
O = cluster.local

[ v3_ca ]
subjectKeyIdentifier = hash
authorityKeyIdentifier = keyid:always,issuer
basicConstraints = critical, CA:true
keyUsage = critical, digitalSignature, cRLSign, keyCertSign
EOF

openssl req -x509 -new -nodes -key ca-private.key -sha256 -days 3650 \
  -out ca-root.crt -config ca-openssl.conf

kubectl --namespace kube-system create secret generic cilium-ztunnel-secrets \
  --from-file=bootstrap-private.key=bootstrap-private.key \
  --from-file=bootstrap-root.crt=bootstrap-root.crt \
  --from-file=ca-private.key=ca-private.key \
  --from-file=ca-root.crt=ca-root.crt

echo "ztunnel secrets created in kube-system/cilium-ztunnel-secrets"
The Control Plane Is Not One Thing: Istio Ambient vs Cilium Mesh
Both Istio ambient and Cilium Service Mesh run a per-node proxy named ztunnel. That is not a coincidence — Cilium 1.19+ builds on the upstream ztunnel project that originated in Istio's ambient work, with joint engineering between Isovalent and Microsoft. The difference is what the rest of the stack looks like around that proxy, and it matters for your migration path.
| Dimension | Cilium Mesh (1.20) | Istio Ambient |
|---|---|---|
| L4 datapath | eBPF in-kernel; ztunnel for HBONE mTLS on enrolled namespaces (Beta) | ztunnel per node (Rust); all in-mesh TCP via HBONE |
| L7 datapath | Per-node Envoy, used only for L7-selected flows | Optional waypoint proxies (Envoy deployments), destination-enforced |
| Control plane | Cilium agents + operator; xDS to node Envoy | istiod; separate xDS streams to ztunnel and waypoints |
| mTLS scope | Namespace label opt-in (io.cilium/mtls-enabled=true); TCP only; in-cluster only | Namespace label (istio.io/dataplane-mode=ambient); TCP; plaintext fallback policy-controlled |
| L7 policy API | CiliumNetworkPolicy L7 rules; upstream KNP/KCNP tiers | AuthorizationPolicy (L4 at ztunnel, L7 at waypoint) |
| North-south | Gateway API (HTTP, gRPC, TLS, TCP, UDP routes), Ingress controller | Ingress Gateways + Gateway API; waypoint-mediated ingress |
| Multi-cluster | ClusterMesh (Global Services, MCS-API stable in 1.20) — incompatible with ztunnel today | East-west and multi-network gateways; no ClusterMesh equivalent |
| Day-2 upgrades | DaemonSet rollout; L7 flows th ... [OUTPUT TRUNCATED - 744 chars omitted out of 50,674 total] ... it containers delay pod readiness | None — pods never wait for a proxy |
| Per-pod added latency | Two extra hops (sidecar in/out) | Zero for L3/L4; one hop only for L7-selected flows |
The honest caveat: the node-local model moves the capacity conversation from per pod to per node. A node running 30 L7-heavy pods needs an Envoy sized for the sum of their RPS. Right-size the DaemonSet resources (see the Helm values above) and autoscale nodes on Envoy CPU, and the model still wins by an order of magnitude — but "it's the CNI's problem now" is not a capacity plan.
Upgrade Runbook: 1.19 → 1.20
Cilium supports upgrades between consecutive minor versions only, and expects the latest patch of your current minor first. The runbook that avoids the known traps:
# 0. Preflight — do these BEFORE touching Helm
#    a) Kafka/L7 Go-extension policy blocks? (removed in 1.18, will hard-fail)
grep -rn "rules:" policies/ | grep -E "kafka|l7proto" && echo "CLEAN FIRST"
#    b) CiliumNodeConfig on v2alpha1? (removed in 1.20)
kubectl get ciliumnodeconfigs.cilium.io -A -o jsonpath='{range .items[*]}{.apiVersion}{"
"}{end}' | sort -u
#    c) TLSRoute users: back up now
kubectl get tlsroutes.gateway.networking.k8s.io -A -o yaml > tlsroutes-backup.yaml

# 1. Latest patch of current minor
helm upgrade cilium cilium/cilium --version 1.19.7 -n kube-system --reuse-values --wait

# 2. Gateway API CRDs to v1.6.1 — Experimental channel for TLSRoute v1alpha2
#    (see full CRD commands in the installation section above)

# 3. Cilium 1.20.2
helm upgrade cilium cilium/cilium --version 1.20.2 \
  -n kube-system --reuse-values --wait

# 4. Post-upgrade verification
cilium status --wait
cilium connectivity test --force
kubectl -n kube-system rollout status ds/cilium ds/cilium-envoy
hubble observe --since 10m --verdict DROPPED | head   # watch for surprise drops

# 5. Watch the config-drift metric 1.20 added
#    cilium_configDrift* — keys the agent hasn't applied yet = restart needed
kubectl -n kube-system exec ds/cilium -- cilium-dbg metrics list | grep -i drift
Deprecated in 1.20 — schedule the migration now: Mutual Authentication (the pre-ztunnel feature, Beta since 1.14) is deprecated with removal planned. hubble.preferIpv6 moves to top-level preferIpv6. dnsProxy.preCache goes away in 1.21. cilium-dbg bgp commands and the local REST BGP API are deprecated in favor of the hive shell (cilium-dbg shell -- bgp/peers --format detailed). The ClusterMesh cert validity default is now one year — if you use the Helm generation mode, certs renew only when the chart re-renders, so upgrade at least once a year or switch to cronJob/certmanager modes.
Edge Cases That Will Bite Someone on Your Team
- ztunnel + L7 policy on the same flow. L4 policy sees the HBONE tunnel; L7 policy on enrolled pods must be designed with the redirect in mind (docs: only rules directly targeting port 15008 behave classically). Test in audit mode first.
- netkit +
bpf.tproxy=true. Incompatible — the agent fails to start, or auto mode silently reverts to veth. If you see "Device Mode: veth [Configured: auto]" on a 6.8+ kernel node, this is why. - GKE Datapath V2 / managed Cilium variants. Cloud-managed Cilium (AKS Azure CNI powered by Cilium, GKE Datapath V2, EKS Cilium) does not expose the full Helm surface. ztunnel and datapath plugins are self-managed-Cilium features first; check your provider's support matrix before designing around them.
- Envoy per node and HPA storms. Scale-up events concentrate L7 load on few nodes before the scheduler spreads pods. Envoy limits are a platform-level guarantee; set them as if the node's whole L7 budget depends on them.
- Source-IP verification per-pod. The new 1.20 per-pod opt-out requires both a namespace annotation (
config.cilium.io/delegate-source-ip-verification: "true") and a pod annotation (config.cilium.io/disable-source-ip-verification: "true"). Lock down who can annotate namespaces with RBAC, or you have re-opened spoofing cluster-wide.
Who Should Skip This Entirely
- Teams whose mesh need is "mTLS between two clusters." Run ClusterMesh + IPsec/WireGuard. ztunnel is single-cluster and ClusterMesh-incompatible today; the older transparent encryption is stable, in-kernel, and zero-mTLS-ops.
- Platforms standardized on Istio ambient with waypoint L7 routing. Stay. The docs-supported coexistence config is Cilium-as-CNI with
kubeProxyReplacement: false(or the socketLB/cni.exclusive trio) — running two HBONE ztunnels or two L7 engines "for completeness" buys you twice the Beta risk and no additional capability. - Kafka L7 policy shops. That capability is gone (removed 1.18). Cilium mesh will not give it back; budget for a different approach (mesh-less Kafka ACLs, or an Envoy-filter-based gateway in front of the brokers).
- Anyone on < 5.10 kernels without an upgrade path. Hard requirement, no workaround.
The Verdict
Cilium Service Mesh in 1.20 is the first release where the honest answer to "do we need a separate mesh?" is "usually not." mTLS that covers same-node traffic, Gateway API with ExternalAuth and L4 routes, tiered cluster-wide policy via upstream KCNP, policy-correlated audit trails, and Hubble — all on the DaemonSet upgrade model, all on one Envoy per node.
What keeps it from being a blanket recommendation is the same thing that has always separated CNI-as-mesh from a real mesh: the L7 control plane. Cilium's L7 story is Gateway API plus CiliumNetworkPolicy — powerful, standards-aligned, and deliberately narrower than Istio's per-workload routing surface. If your platform's product is rich per-service traffic management, you will still run Istio ambient next to Cilium, in the documented coexistence mode. If your platform's product is paved roads with sane defaults — the platform-monkey thesis — then the CNI you already pay for just absorbed your mesh budget, and ztunnel's Beta label is the only reason not to start the rollout planning today.
Plan it as: transparent encryption now (stable), Gateway API north-south now (GA), L7 policy where the audit stream proves it (1.20 correlation makes this safe), ztunnel in one non-ClusterMesh cluster this quarter (Beta, metrics are finally there), and a re-evaluation of the Istio question when ztunnel goes stable and the ClusterMesh incompatibility is resolved.
Mermaid: Component Architecture
The control-plane and data-plane view of a full 1.20 mesh deployment — who talks to whom, and which components share a node:
flowchart TB
    subgraph K8s["Kubernetes API Server (v1.37)"]
        CRDs["CRDs: CiliumNetworkPolicy / CiliumClusterwideNetworkPolicy
ClusterNetworkPolicy (KCNP, v1alpha2) / CiliumNodeConfig (v2)
Gateway API v1.6.1 / CiliumEnvoyConfig"]
    end

    subgraph OPS["Platform Operators (kube-system)"]
        OP["cilium-operator (2 replicas)
IPAM · ztunnel enrollment reconciler · MCS-API · BGP"]
        HR["hubble-relay"]
        CM["clustermesh-apiserver
(not with ztunnel!)"]
    end

    subgraph NODE1["Node 1"]
        AG1["cilium agent
(eBPF programs: policy, BPF LB, TPROXY)"]
        EN1["cilium-envoy
(L7 + Gateway API)"]
        ZT1["ztunnel
(HBONE mTLS, 15008)"]
        P1["pod A (mtls-enabled ns)"]
        P2["pod B"]
    end

    subgraph NODE2["Node 2"]
        AG2["cilium agent"]
        EN2["cilium-envoy"]
        ZT2["ztunnel"]
        P3["pod C (mtls-enabled ns)"]
    end

    K8s -->|watch & reconcile| AG1
    K8s -->|watch & reconcile| AG2
    K8s --> OP
    OP -->|SPIFFE registration, spire CA mode| K8s
    AG1 -->|xDS| EN1
    AG2 -->|xDS| EN2
    AG1 -->|ZDS: pod metadata| ZT1
    AG2 -->|ZDS| ZT2
    P1 -->|iptables redirect in netns| ZT1
    P2 -->|in-kernel L3/L4, no L7 rule| AG1
    ZT1 -->|HBONE mTLS :15008| ZT2
    ZT2 --> P3
    AG1 -.->|flow events| HR
    AG2 -.->|flow events| HR
    CM -.->|global services, MCS-API| AG1
    CM -.-> AG2
The Demo App: Complete Runnable Manifests
Everything below assumes this three-tier demo — the same payments/gateway namespaces used in the policy sections. Apply it and every command in this guide runs as written:
# demo-app.yaml — namespaces, deployments, services
apiVersion: v1
kind: Namespace
metadata:
  name: gateway
---
apiVersion: v1
kind: Namespace
metadata:
  name: payments
  labels:
    io.cilium/mtls-enabled: "true"     # ztunnel enrollment (requires ztunnel install)
---
apiVersion: apps/v1
kind: Deployment
metadata:
  name: api-gateway
  namespace: gateway
spec:
  replicas: 2
  selector:
    matchLabels: {app: api-gateway}
  template:
    metadata:
      labels: {app: api-gateway}
    spec:
      containers:
      - name: gateway
        image: ghcr.io/cilium/json-mock:http-v1.3.12
        ports: [{containerPort: 8080}]
        resources:
          requests: {cpu: 100m, memory: 64Mi}
          limits: {cpu: 500m, memory: 128Mi}
---
apiVersion: v1
kind: Service
metadata:
  name: api-gateway
  namespace: gateway
spec:
  selector: {app: api-gateway}
  ports: [{port: 8080, targetPort: 8080}]
---
apiVersion: apps/v1
kind: Deployment
metadata:
  name: payments
  namespace: payments
spec:
  replicas: 3
  selector:
    matchLabels: {app: payments}
  template:
    metadata:
      labels: {app: payments}
    spec:
      containers:
      - name: payments
        image: ghcr.io/cilium/json-mock:http-v1.3.12
        ports: [{containerPort: 8080}]
        resources:
          requests: {cpu: 100m, memory: 64Mi}
          limits: {cpu: 500m, memory: 128Mi}
---
apiVersion: v1
kind: Service
metadata:
  name: payments
  namespace: payments
spec:
  selector: {app: payments}
  ports: [{port: 8080, targetPort: 8080}]
# Smoke test: connectivity, then prove mTLS and L7 policy on the wire
kubectl apply -f demo-app.yaml
kubectl -n gateway run test --image=cilium/cilium:1.20.2 --command -- sleep 3600
kubectl -n gateway exec test -- curl -s http://payments.payments:8080/ | head -3
# mTLS proof: capture on the source node, HBONE port 15008
kubectl -n kube-system exec -ti ds/cilium -- bash -c \
"apt-get -y install tcpdump >/dev/null 2>&1; tcpdump -i eth0 port 15008 -c 5"
# L7 policy proof: apply the L7 policy from the previous section, then
hubble observe --namespace payments --protocol http --since 2m -o compactTraffic Engineering: Maglev, Weights, and Traffic Distribution
Two 1.20 features turn Cilium's BPF load balancer from "evenly split" into a real traffic-engineering surface. Both matter to platform teams running canaries and maintenance windows.
Maglev weights via EndpointSlice annotations. For selectorless Services backed by manually managed EndpointSlices, annotate each slice with service.cilium.io/weight (0–65535, relative). A 70/30 canary becomes a two-line annotation change, and weight 0 is a connection-preserving drain: existing connections keep flowing, but no new ones are steered there — the clean maintenance-window primitive that mesh-free platforms have lacked:
apiVersion: v1
kind: Service
metadata:
  name: payments-stable
  namespace: payments
  annotations:
    service.cilium.io/lb-algorithm: maglev
spec:
  type: ClusterIP
  ports: [{name: http, port: 8080, protocol: TCP, targetPort: 8080}]
  # no selector: backends come from the EndpointSlices below
---
apiVersion: discovery.k8s.io/v1
kind: EndpointSlice
metadata:
  name: payments-stable-primary
  namespace: payments
  labels:
    kubernetes.io/service-name: payments-stable
  annotations:
    service.cilium.io/weight: "70"        # 70% of new connections
addressType: IPv4
ports: [{name: http, protocol: TCP, port: 8080}]
endpoints:
  - addresses: ["10.0.0.11"]
  - addresses: ["10.0.0.12"]
---
apiVersion: discovery.k8s.io/v1
kind: EndpointSlice
metadata:
  name: payments-stable-canary
  namespace: payments
  labels:
    kubernetes.io/service-name: payments-stable
  annotations:
    service.cilium.io/weight: "30"        # canary share; "0" = drain
addressType: IPv4
ports: [{name: http, protocol: TCP, port: 8080}]
endpoints:
  - addresses: ["10.0.1.21"]
  - addresses: ["10.0.1.22"]
Traffic distribution with the standard Kubernetes field. Cilium 1.20 honors the upstream trafficDistribution values PreferSameZone and PreferSameNode (beyond the older PreferClose) — keeping traffic local for latency and for cross-zone transfer costs, with graceful fallback when no local backend is healthy. Because it is the standard field, the same Service spec behaves consistently on any conformant implementation:
apiVersion: v1
kind: Service
metadata:
  name: payments
  namespace: payments
spec:
  trafficDistribution: PreferSameZone
  selector: {app: payments}
  ports: [{protocol: TCP, port: 8080, targetPort: 8080}]
  type: ClusterIP
The Monitoring Stack: Prometheus + Grafana for Mesh Health
Hubble metrics feed the standard Prometheus scrape of the agents and relay. The alerting rules below cover the four failure modes that actually page platform teams: agent down, endpoint regeneration storms, policy drops, and ztunnel enrollment failures:
apiVersion: monitoring.coreos.com/v1
kind: PrometheusRule
metadata:
  name: cilium-mesh-alerts
  namespace: kube-system
  labels:
    release: prometheus            # match your Prometheus operator's ruleSelector
spec:
  groups:
  - name: cilium-datapath
    rules:
    - alert: CiliumAgentDown
      expr: cilium_agents_up == 0 or absent(cilium_agents_up)
      for: 5m
      labels: {severity: critical}
      annotations:
        summary: "Cilium agent is down on {{ $labels.k8s_node }}"
    - alert: CiliumEndpointRegenerationStalled
      expr: rate(cilium_endpoint_regenerations_total{outcome="failure"}[5m]) > 0.1
      for: 15m
      labels: {severity: warning}
      annotations:
        summary: "Endpoint regeneration failures on {{ $labels.k8s_node }}"
    - alert: CiliumPolicyDropsHigh
      expr: rate(hubble_drop_total[5m]) > 10
      for: 10m
      labels: {severity: warning}
      annotations:
        summary: "Sustained policy drops — possible rollout regression"
  - name: ztunnel
    rules:
    - alert: ZtunnelEnrollmentFailures
      expr: rate(cilium_operator_ztunnel_enrollment_ops_total{status="error"}[10m]) > 0
      for: 15m
      labels: {severity: warning}
      annotations:
        summary: "ztunnel namespace enrollment is failing — pods not getting mTLS"
    - alert: ZtunnelConnectionIssues
      expr: rate(ztunnel_connection_errors_total[10m]) > 0.5
      for: 10m
      labels: {severity: warning}
      annotations:
        summary: "ztunnel is failing a material share of HBONE connections"
Dashboard queries that matter for a mesh rollout (paste into any Grafana panel against the Hubble metrics):
# 1. mTLS coverage: share of flows on the HBONE port vs total east-west
sum(rate(hubble_flows_processed_total{protocol="TCP"}[5m]))

# 2. Policy verdicts over time (enforcement regressions show here first)
sum by (verdict) (rate(hubble_verdicts_total[5m]))

# 3. Config drift: unapplied ConfigMap keys = agent restart needed (new in 1.20)
cilium_configdrift_keys_total{status="pending"}

# 4. Envoy L7 load per node — the shared-proxy contention signal
sum by (k8s_node) (rate(envoy_http_downstream_rq_total[5m]))
A note on the metric names above: scrape them once and confirm the exact series names your chart version exposes before committing the rules to your alerting repo — Cilium's metric names have shifted across minors (the 1.20 upgrade guide documents several renames, e.g. per-node IPAM metrics replacing cilium_operator_ipam_ips). Treat alert names as code: version them, test them in audit, and grep the exposition endpoint (kubectl -n kube-system exec ds/cilium -- cilium-dbg metrics list) when a panel goes flat.
Troubleshooting: The Five Failures You Will Actually Hit
1. "Gateway API created the LB, but connections time out"
Symptom: the Gateway's Service gets an external IP; curls hang. Cause: L7 traffic never reaches Envoy — the node lacks the iptables/netfilter modules for TPROXY (bpf.tproxy=false default). Fix: verify CONFIG_NETFILTER_XT_TARGET_TPROXY on the node, or switch to the beta eBPF TPROXY (bpf.tproxy=true — remembering it is incompatible with netkit datapath mode).
2. "I labeled the namespace but pods aren't encrypted"
Symptom: tcpdump -i eth0 port 15008 shows nothing. Causes, in order of likelihood: (a) ztunnel not actually enabled — check kubectl -n kube-system describe cm cilium-config | grep enable-ztunnel -A2; (b) the destination namespace is not enrolled (both endpoints must be); (c) host-networked pods — they are skipped by design; (d) UDP flow — ztunnel is TCP-only. Fix: enroll both ends, re-check the StateDB table (cilium-dbg statedb dump | jq '."mtls-enrolled-namespaces"').
3. "L4 policy stopped matching after ztunnel enrollment"
Symptom: previously-working CiliumNetworkPolicies drop or allow unexpectedly on enrolled namespaces. Cause: traffic is encrypted inside the pod netns before Cilium's L4 engine sees it — policy now observes the tunnel, and only rules targeting the HBONE port (15008) behave classically. Fix: redesign the policy set for enrolled namespaces around the documented interaction, validate with hubble observe --verdict DROPPED, and use audit mode with policy correlation before enforcing.
4. "Upgrade to 1.20 broke TLSRoutes"
Symptom: TLSRoute objects disappear from kubectl get after the CRD update. Cause: the v1.6.1 Standard channel's TLSRoute CRD no longer serves v1alpha2, so existing objects are unreadable by the API server. Fix: restore from backup and install the Experimental channel TLSRoute CRD, which still includes v1alpha2. This is why the runbook backs up TLSRoutes before any CRD change.
5. "Node shows veth on a 6.8+ kernel with datapathMode=auto"
Symptom: cilium-dbg status reports Device Mode: veth [Configured: auto] on modern nodes. Cause: bpf.tproxy=true is set — auto mode deliberately reverts to veth when netkit and eBPF-TPROXY conflict. Fix: decide which feature you want: netkit (drop bpf.tproxy=true) or eBPF TPROXY (accept veth). The 1.20 behavior is documented, not a bug.
Performance: What the Datapath Actually Buys You
Claiming "eBPF is faster" without mechanisms is marketing. The measurable mechanisms in this stack:
- Socket-LB short-circuits service NAT. With kube-proxy, in-cluster traffic to a Service VIP is DNATed in iptables across every packet. Cilium's socket-LB resolves the backend at
connect()time — the kernel attaches the destination directly to the socket, and per-packet NAT disappears from the fast path. - netkit replaces veth overhead. The netkit device (kernel >= 6.8, auto mode in 1.20) eliminates the veth-pair context cost for pod traffic — the reason Meta rolled it out across millions of containers and ByteDance reported ~10% improvement in its tests.
bpf.datapathMode=autois the low-risk adoption path on mixed fleets: probe per node, fall back per node. - L7 is opt-in per flow. The classic mesh tax — every request through a user-space proxy — applies only to flows an L7 rule selects. Everything else stays in-kernel. Your RPS-weighted Envoy sizing should reflect selected flows only.
- Identity aggregation keeps policy enforcement flat. 1.20's wildcard entries for
world/remote-node/cluster-meshmean the BPF policy map no longer scales with remote identity count — the map pressure that previously capped heavily-meshed clusters collapses to a handful of entries. - Smaller CNI binary, faster node bring-up. The CNI plugin went from ~76 MB to ~16 MB in 1.20 — a 79% cut that matters mostly on node scale-up and image-pull-constrained clusters.
What to measure before/after: p50/p99 of pod-to-pod TCP round trips (careful: ztunnel enrollment adds the TLS handshake to first-connection latency by design), Envoy CPU per 1k RPS of L7-selected traffic, and node boot-to-schedulable time. Baseline them on your workloads — the numbers that matter are yours.
Migrating Off Ingress NGINX: The Actual Playbook
The Cilium 1.20 release notes make an aggressive pitch: "If you are still running Ingress NGINX, now is the time to let the CNI you already run take on that traffic management too." Here is what that migration actually looks like, including the parts that hurt.
The mechanical translation
Every NGINX annotation has a Gateway API equivalent, but they are not 1:1 — a rewrite-based path routing becomes a URLRewrite filter, a TLS-secret annotation becomes certificates.refs, and canary weights become weighted backendRefs (or, for selectorless Services, the Maglev slice weights from the traffic section). The docs ship a full "Migrating from Ingress to Gateway" walkthrough with the annotation-to-field mapping tables — start there, not from scratch.
# Before: NGINX Ingress with the usual annotation pile
apiVersion: networking.k8s.io/v1
kind: Ingress
metadata:
  name: payments
  annotations:
    nginx.ingress.kubernetes.io/rewrite-target: /$2
    nginx.ingress.kubernetes.io/ssl-redirect: "true"
spec:
  ingressClassName: nginx
  tls: [{hosts: [payments.example.com], secretName: payments-tls}]
  rules:
  - host: payments.example.com
    http:
      paths:
      - path: /v1(/|$)(.*)
        pathType: ImplementationSpecific
        backend: {service: {name: payments, port: {number: 8080}}}
---
# After: HTTPRoute on the shared Cilium Gateway
apiVersion: gateway.networking.k8s.io/v1
kind: HTTPRoute
metadata:
  name: payments
  namespace: payments
spec:
  parentRefs: [{name: shared-gateway, namespace: gateway-system}]
  hostnames: ["payments.example.com"]
  rules:
  - matches:
    - path: {type: PathPrefix, value: /v1}
    filters:
    - type: URLRewrite
      urlRewrite:
        path: {type: ReplacePrefixMatch, replacePrefix: /}
    backendRefs: [{name: payments, port: 8080}]
What gets better
• One Envoy DaemonSet instead of ingress-controller replicas to size and upgrade
• Namespace-scoped routes — app teams own their objects, RBAC falls out naturally
• Portable manifests: same HTTPRoute runs on Envoy Gateway, Traefik, Istio
• L7 policy and ingress share one datapath and one Hubble view (drops at the edge are visible with policy correlation)
What hurts
• Every chart that templates ingressClassName: nginx and annotations needs a values refactor
• ImplementationSpecific path types must be re-decided explicitly as Exact/PathPrefix/RegularExpression
• Custom snippets / Lua / server-block configs have no Gateway API equivalent — they become separate routes, CiliumEnvoyConfig (admin-only, minimal validation), or app code
• You are now on Gateway API release cadence as well as Cilium's — track CRD versions deliberately
Rollout pattern that works: run both controllers in parallel — Gateway API's Gateway and NGINX's IngressClass can coexist — and cut over host by host via DNS weights. Keep NGINX until every annotation-driven behavior is verified on the Gateway in Hubble (the flow-level comparison between the two paths is your acceptance test), then decommission the controller and reclaim its resource requests.
References & Further Reading
- Cilium Documentation (v1.20.2) — system requirements, Helm reference, upgrade guide, ztunnel encryption guide.
- Cilium 1.20 Release Announcement — Gateway API v1.6 (ExternalAuth, TCPRoute/UDPRoute, ListenerSets), ztunnel improvements, ENI IPv6, datapath plugins.
- Cilium v1.20 CHANGELOG — per-PR attribution for every 1.20 feature and deprecation.
- Cilium Service Mesh Documentation — L7 traffic management, per-node Envoy model, Ingress/Gateway API/GAMMA.
- Ztunnel Transparent Encryption (Beta) — enrollment model, CA backends, limitations, HBONE verification.
- Cilium Gateway API Support — supported resources, CRD install commands, ListenerSets.
- Integration with Istio — the documented coexistence configuration (socketLB.hostNamespaceOnly, cni.exclusive).
- Cilium Upgrade Guide (1.20 notes) — TLSRoute v1 migration, removed options, metrics changes.
- Kubernetes Gateway API — the SIG-Network specification Cilium implements (v1.6.1).
- Istio Ambient Mesh — ztunnel/waypoint architecture for the comparison section.
- cilium/cilium on GitHub — the primary repository.